Multi-View Based Audio Visual Target Speaker Extraction
The github link: https://github.com/b23ca07a/MVTF
MVTF
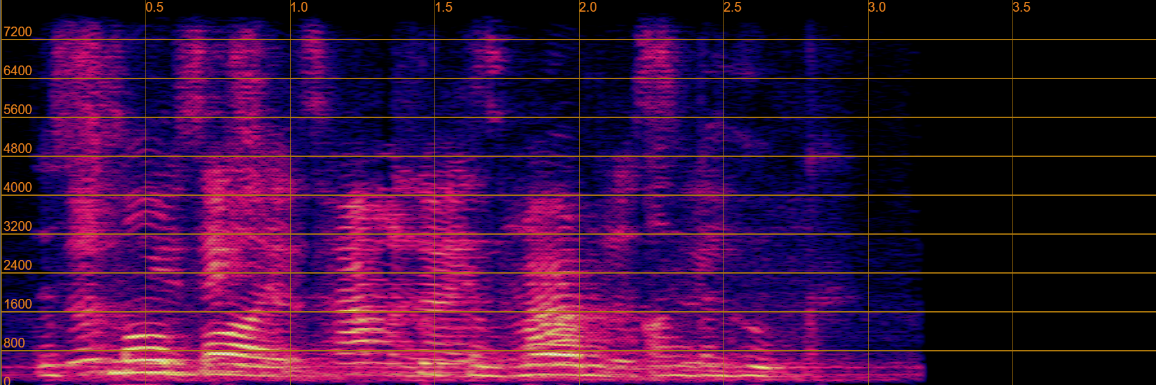
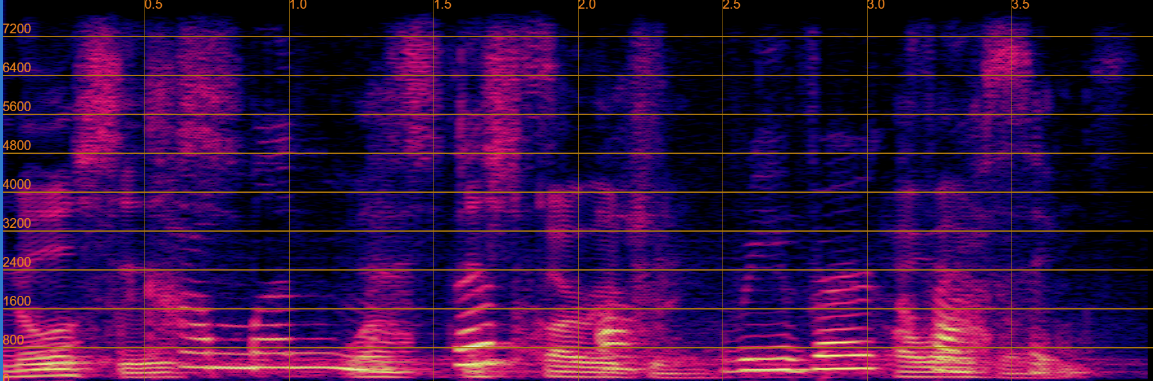
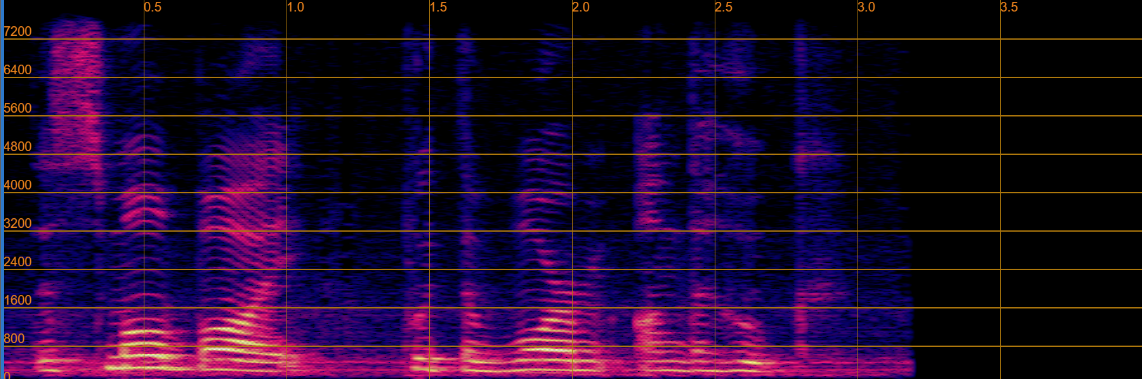
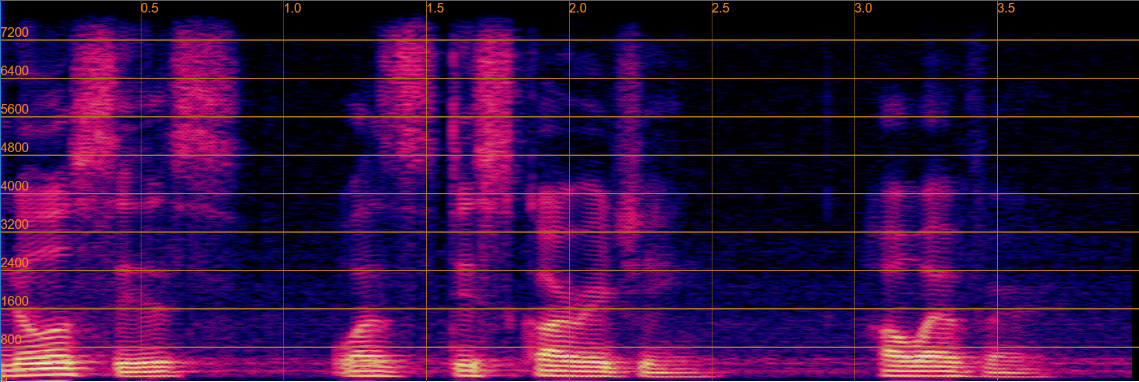
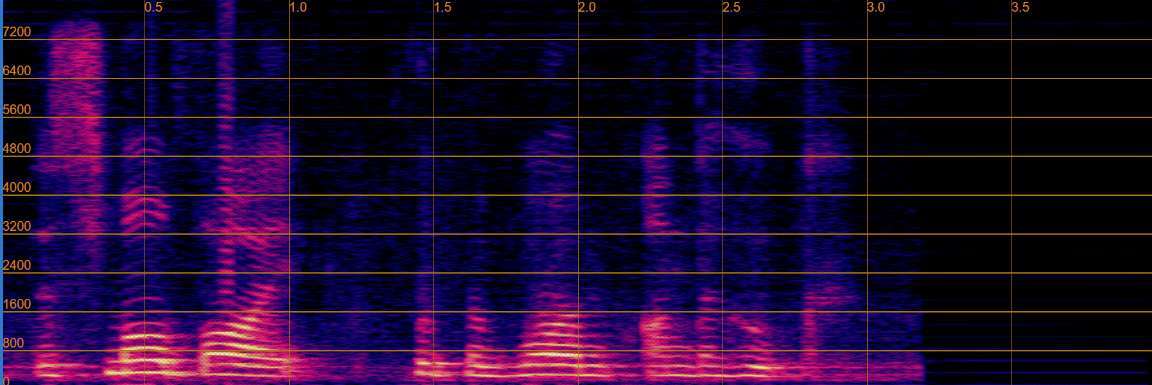
The following presents the results of each evaluation sentence using repeated front view to MVTF-Gridnet respectively. The mixture, target, and result are shown in the table. The audio and spectrum are also provided for each sentence.| Mixture | 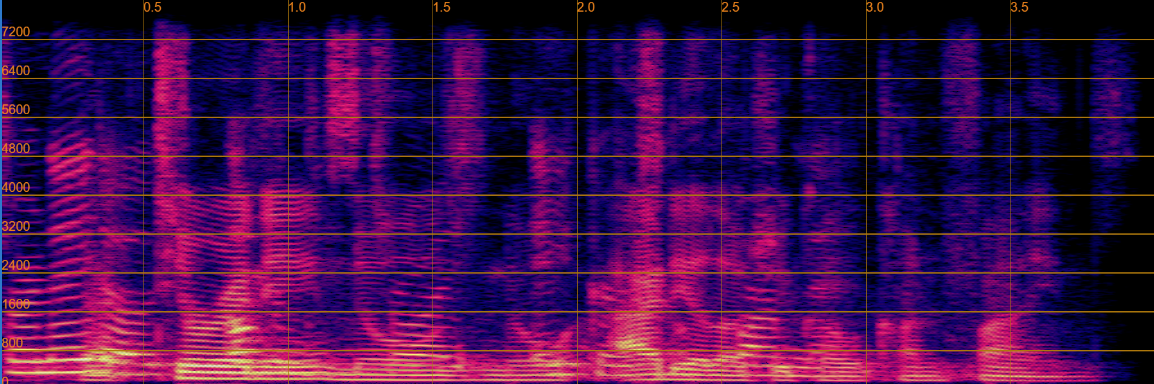 |
 |
 |
| (Audio) | |||
| Target | 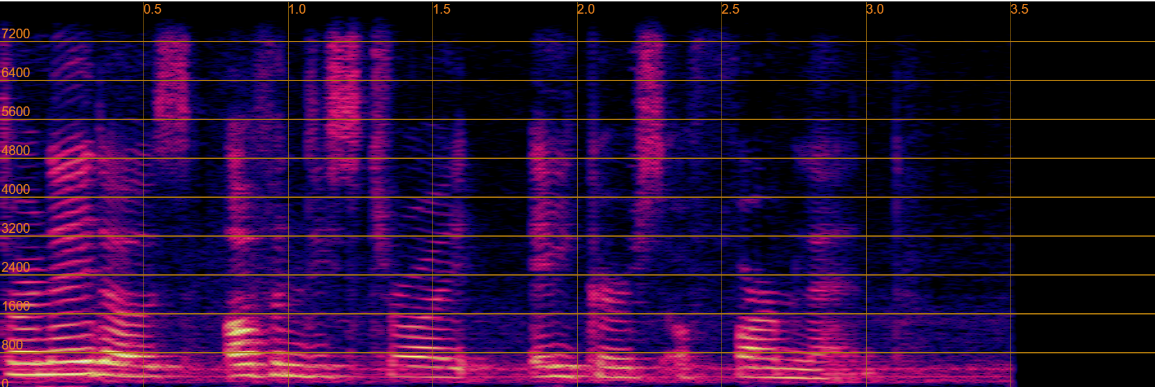 |
 |
 |
| (Audio) | |||
| MVTF-Result | 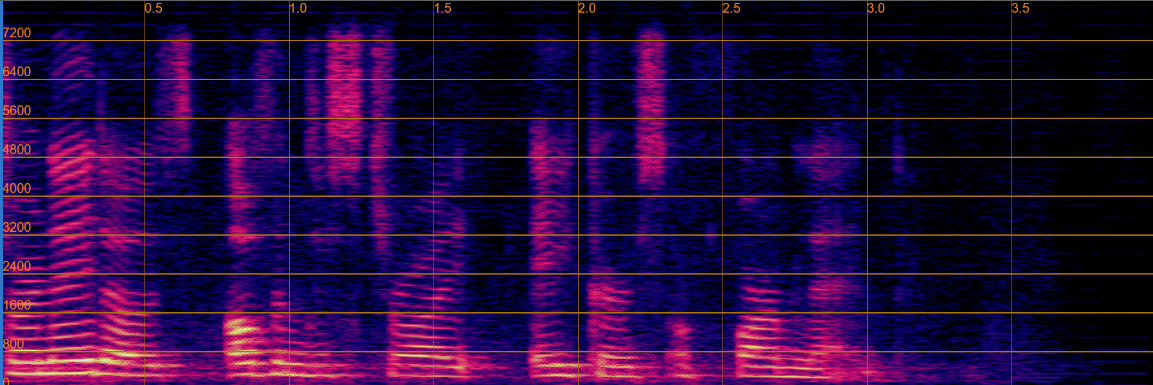 |
 |
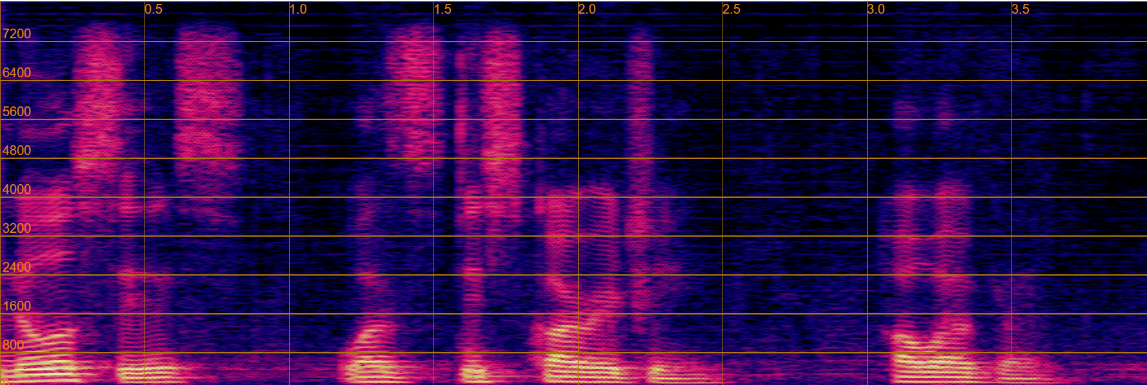 |
| (Audio) |